Case study 01 of 03 · Semantic AI benchmark
A semantic layer makes an AI analyst consistent. Does it make it right?
I built a benchmark to answer that properly: one frozen ecommerce dataset with five planted data problems, ground truth computed independently, and an LLM agent answering the same 20 business questions twice, once against raw BigQuery tables and once through a governed Cube semantic layer. This first part runs entirely on Google Cloud.
BigQuery EU
Cube Core v1.7.46
Gemini 3.8 Flash on Vertex AI EU
Claude Opus 5 judge
theLook eCommerce
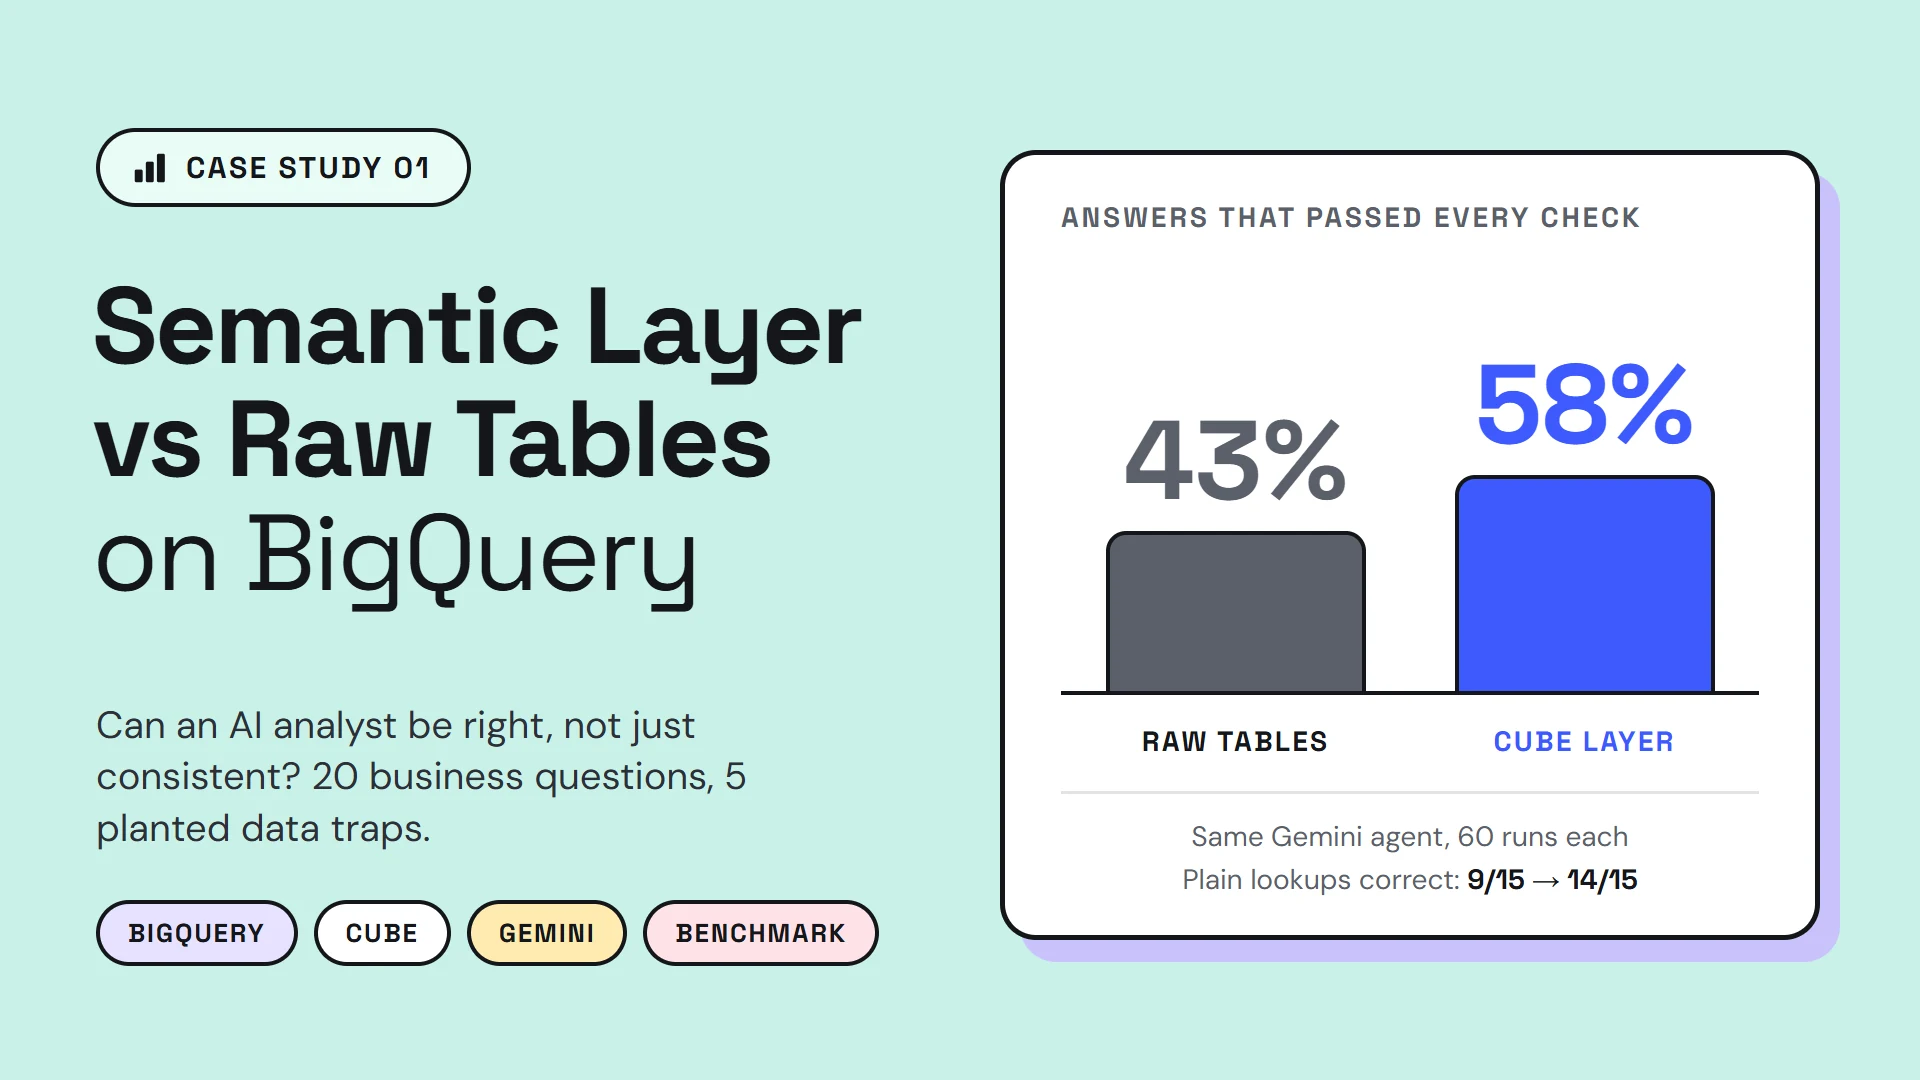
58% vs 43%
of answers passed through the governed layer vs raw tables, same Gemini agent, 60 runs each
14/15 vs 9/15
straightforward lookups answered correctly, the questions leaders assume are safe
22/22
layer correctness checks within 0.5% of ground truth, run without any LLM involved
$10
to run the full 60-answer evaluation on Gemini through Cube ($7 on raw tables)
My role: solo build, covering benchmark design, star schema, semantic layer, agent and evaluation harness.